What is Cerebras AI: The Revolution in AI Inference and its Integration with NAiOS.net*
In the fast-paced ecosystem of artificial intelligence, processing speed and responsiveness have become the main bottlenecks for companies. As language models (LLMs) grow in size and complexity, traditional GPU-based infrastructures often struggle to maintain low latency without skyrocketing costs. It is in this scenario that Cerebras AI (https://www.cerebras.ai/) emerges, a company that is redefining the limits of hardware for artificial intelligence.
In this article, we will explore in depth what Cerebras is, why its new CS-4 accelerator is changing the game, how it is impacting various industries, and most importantly, how you can leverage all this potential through its integration with naios.net.
What is Cerebras AI?
Cerebras Systems is a technology company specialized in creating hardware and software designed exclusively to accelerate artificial intelligence. Unlike traditional approaches that connect thousands of small chips (GPUs) through complex networks, Cerebras has adopted a radically different approach: the Wafer-Scale Engine (WSE).
Instead of cutting a silicon wafer into hundreds of individual chips, Cerebras uses the entire wafer to create a single giant processor. This eliminates communication delays between chips, allowing for massive bandwidth and processing speed that conventional architectures simply cannot match.
The result of this innovation is a platform that enables training, fine-tuningFine-TuningRetraining a model with specific data for a use case, and serving AI models on a single infrastructure, optimizing the entire machine learning lifecycle.
Cerebras CS-4: The Fastest AI, Now Even Faster
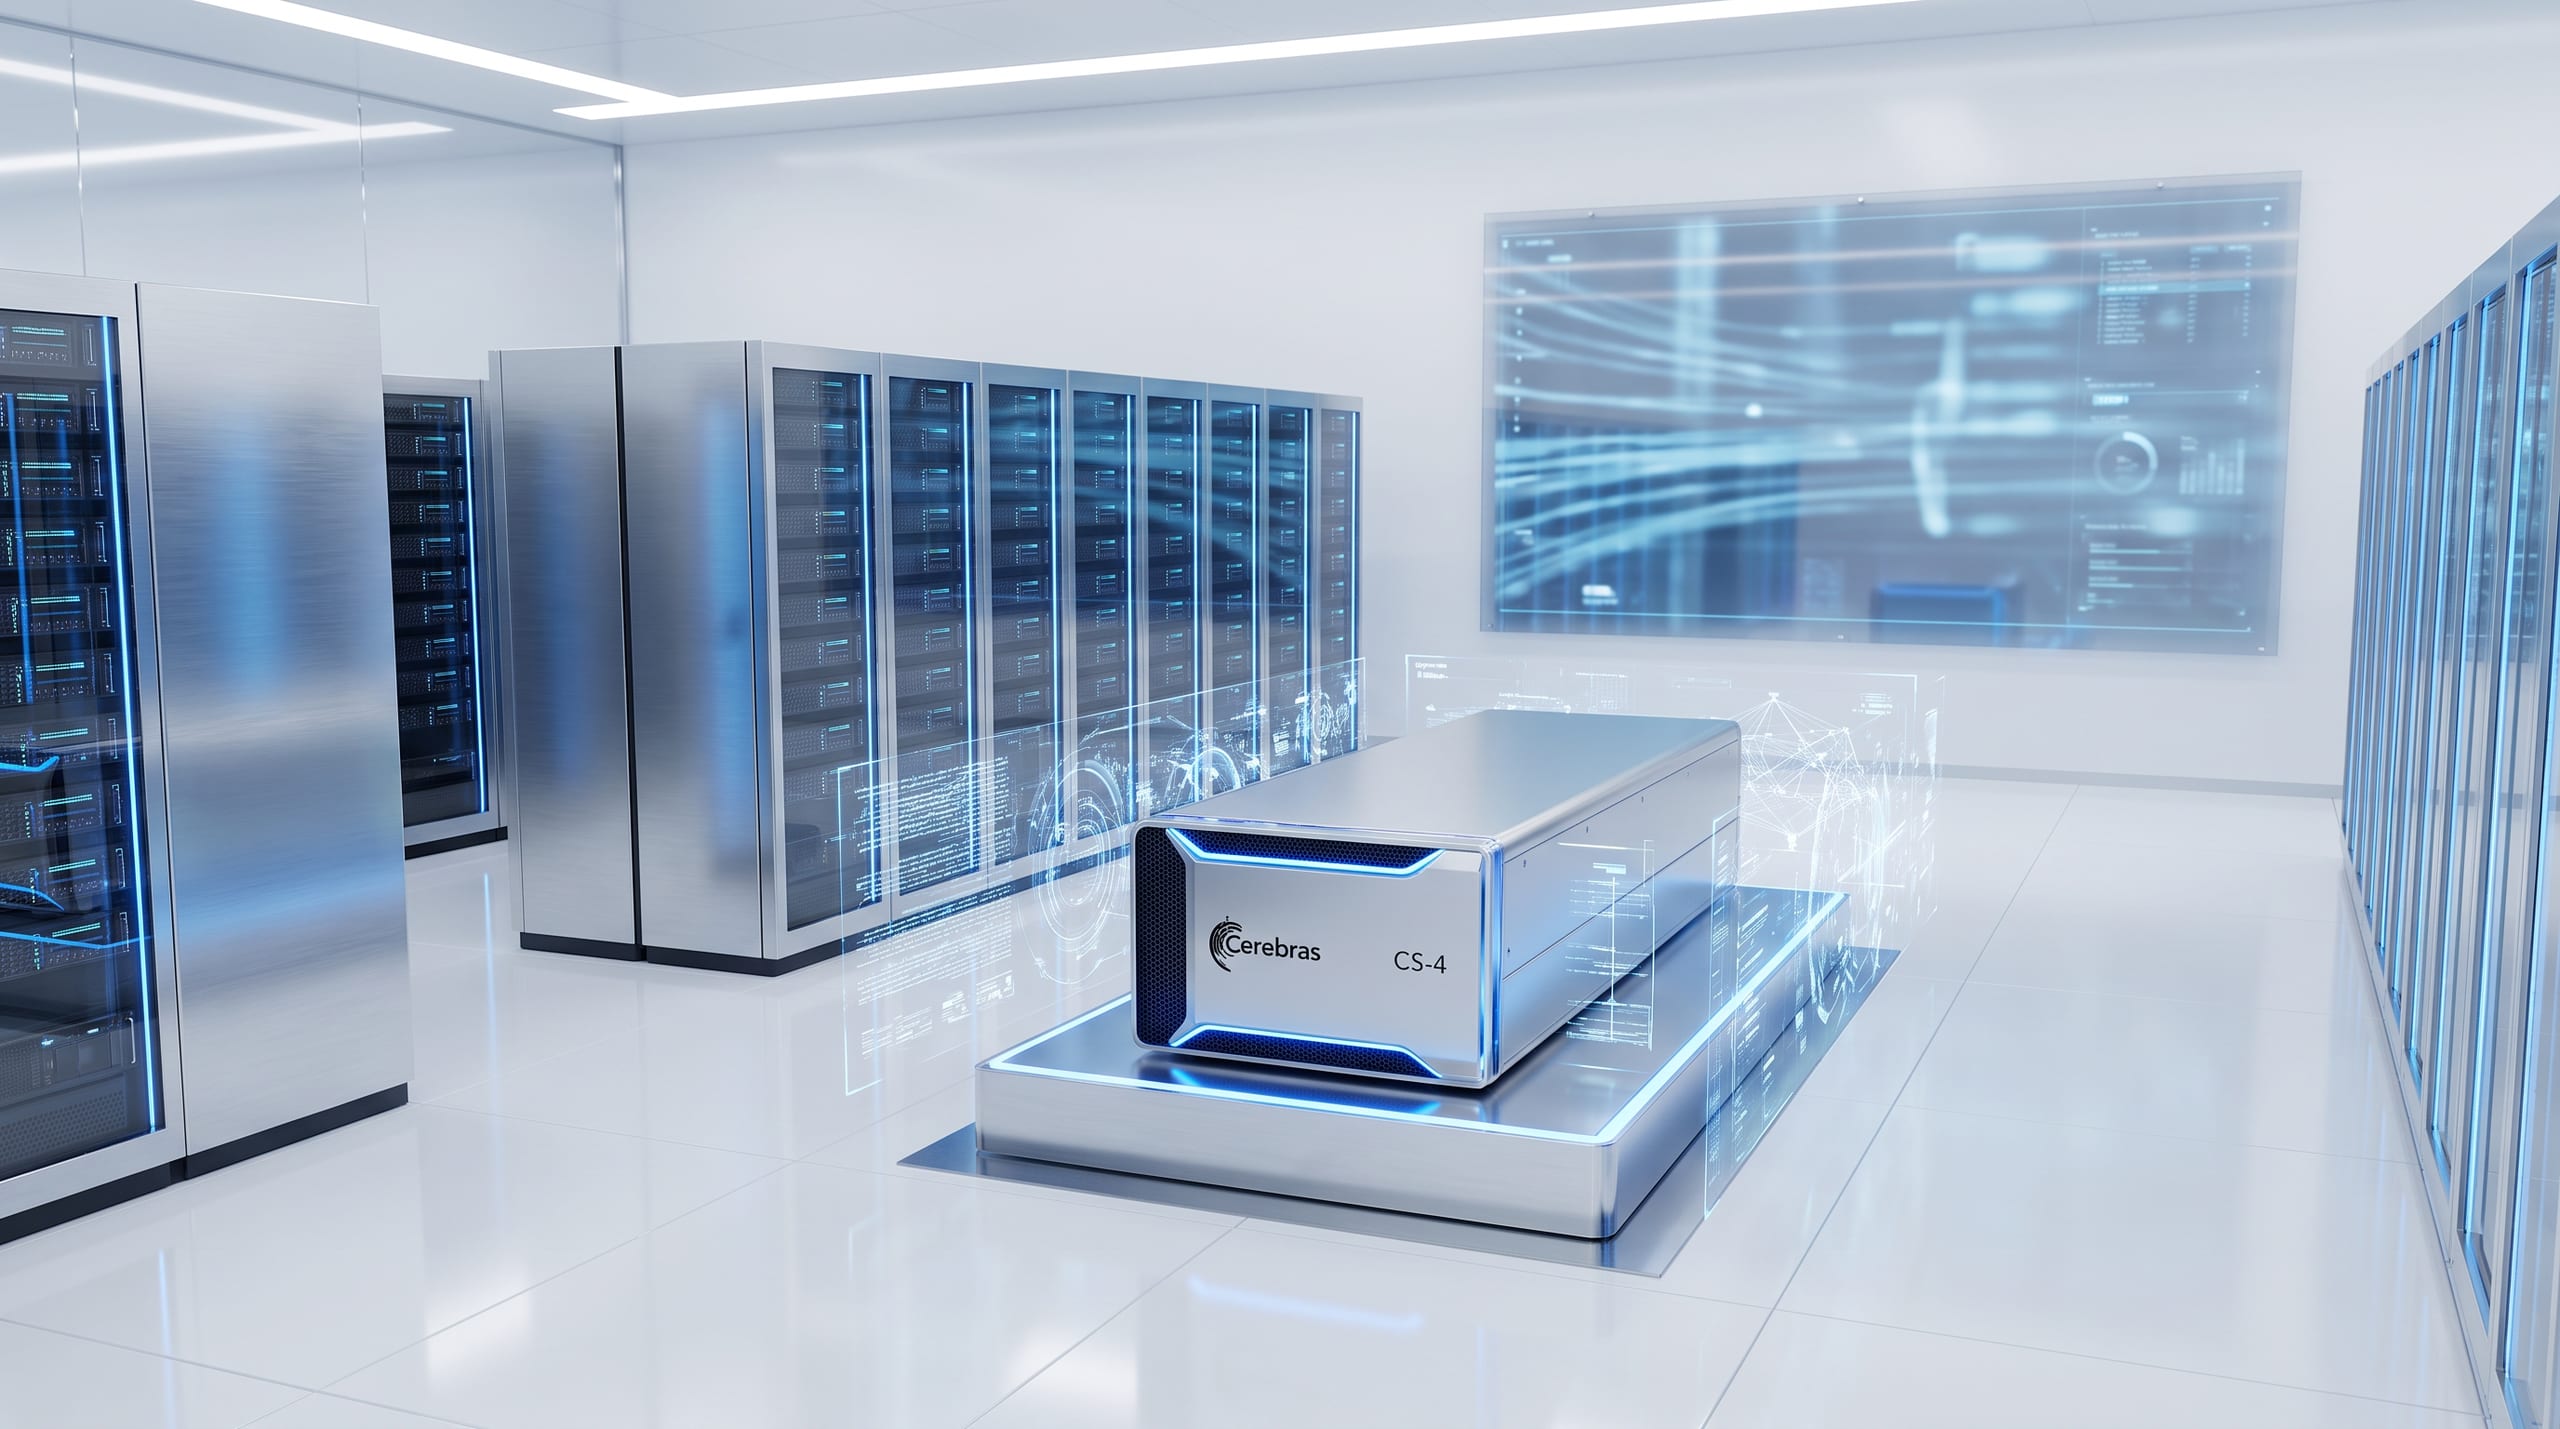
The company's current flagship product is the Cerebras CS-4, a rack-scale solution that offers inference up to 30 times faster compared to traditional GPUs. Designed for hyperscale deployments, the CS-4 positions itself as the fastest infrastructure in the world for "Frontier AIFrontier ModelsThe most advanced and powerful models at all times" (the most advanced AI models).
To put this speed into perspective, cutting-edge models like OpenAI's GPT-5.6 Sol Ultrafast are available on the Cerebras platform running at astonishing speeds of up to 750 tokens per second. Other leading models that leverage this architecture include QWEN 3.8 27B, Kimi K2.6, and Codex-Spark.
The Alliance with AMD for Disaggregated Inference
Cerebras does not work in isolation. Its recent partnership with AMD demonstrates an innovative approach called "disaggregated inference." In this architecture, AMD Helios systems are combined with Cerebras' Wafer-Scale Engine. AMD handles the "prefill" (the initial processing of context) with high performance, while Cerebras takes care of token generation at ultra-fast speeds. This synergy maximizes efficiency and drastically reduces response time.
Competitive Advantages of Cerebras
Adopting Cerebras technology offers tangible benefits that allow companies to build products that were previously unfeasible due to latency limitations:
Unprecedented speed and quality: With faster inference, models have a greater "latency budget" to perform complex reasoning (Chain of ThoughtChain of Thought (CoT)Technique where AI thinks step-by-step before responding) without keeping the user waiting. This translates into higher quality responses in the same time.
Leadership in Price-Performance: Cerebras allows for a drastic reduction in AI infrastructure costs compared to GPU-based clouds, achieving performance up to 30 times higher.
Ease for Developers: The platform is proven at enterprise scale. Developers can start using it in less than 30 seconds thanks to its drop-in compatibility with the OpenAI API.
Full cycle on one platform: You can start with ultra-fast inference and later perform fine-tuning or pre-training with your own data to optimize models for your specific use cases.
Use Cases and Testimonials from Industry Leaders
The speed of Cerebras enables new paradigms of human-computer interaction. Some of the most innovative companies in the world are already leveraging this technology:
Software Development at the Speed of Thought: Companies like Lovable and Cognition use Cerebras to have their coding agents respond instantly. As Anton Osika, CEO of Lovable, notes: "Cerebras helps us make Lovable respond as quickly as our customers think." This allows for programming, debugging, and refactoring in real-time without losing the workflow.
Uninterrupted AI AgentsAI AgentsSystems that execute multi-step tasks without constant supervision: For companies like NinjaTech, speed ensures that multi-step workflows run without delays or timeouts.
Instant Responses and Deep Reasoning: Business search platforms like AlphaSense and Notion use Cerebras to provide deep searches and complex analyses in less than a second.
Smooth Voice Interactions: For conversational AI (like Tavus or LiveKit), ultra-low latency is vital. Cerebras enables instant and accurate voice responses, making interactions feel truly human.
Advances in Health and Science: In the medical sector, the impact is life-saving. Mayo Clinic uses Cerebras to quickly analyze genomic data and find suitable treatments, reducing the physical burden on patients. Similarly, GSK and Argonne National Laboratory accelerate drug discovery and predict responses to cancer medications, achieving in months what previously took years.
Validation from Tech Giants: Leaders like OpenAI, Meta, and AWS integrate Cerebras solutions to diversify their computing portfolio, ensuring low-latency inference and high performance at a global scale.
Flexible Deployment Options
Cerebras understands that every company has unique security and regulatory compliance requirements. Therefore, it offers three deployment modalities:
Cloud: Serves open models in seconds via an API key at its public endpoint, choosing from a regularly updated catalog.
Dedicated: Cloud infrastructure reserved exclusively for your company's workloads, ensuring predictable performance.
On-Premise: Deployment of Cerebras' physical infrastructure in your own data centers. Ideal for keeping AI within your region, complying with strict data residency obligations and regulatory compliance frameworks.
Seamless Integration with Naios.net
Having access to the fastest hardware in the world is only half the equation; the other half is how to orchestrate, manage, and deliver that AI to your end users or business processes. Here is where naios.net comes into play.
Naios.net is a comprehensive platform designed to facilitate the adoption, management, and scalability of artificial intelligence solutions in corporate environments. The great news is that naios.net is fully integrable with Cerebras AI.
What does this integration mean for your company?
By combining the massive processing power of Cerebras with the versatility of naios.net, companies gain an unparalleled end-to-end AI solution:
Simplified Orchestration: Naios.net acts as the operational brain of your AI applications. You can design workflows, manage prompts, and configure intelligent agents from its intuitive interface, while Cerebras handles the heavy computing in the backend.
Seamless Transition (Drop-in): Since Cerebras is compatible with the OpenAI API, connecting naios.net to the Cerebras infrastructure requires minimal changes in configuration. You simply point the naios.net endpoints to Cerebras and enjoy a speed boost of up to 30x.
Real-Time AI Agents: If you use naios.net to create voice assistants, customer service copilots, or financial analysis agents, the integration with Cerebras ensures that these agents operate without the typical latency (lag) that frustrates users, processing hundreds of tokens per second.
Cost-Effective Scalability: Manage your users, quotas, and analytics on naios.net while benefiting from the cost-efficiency (price-performance) that Cerebras' inference cloud offers.
Below is an illustration of how the architecture of this powerful integration works:
classDef naios fill:#007BFF,stroke:#0056b3,stroke-width:2px,color:#fff;
classDef cerebras fill:#FF4500,stroke:#cc3700,stroke-width:2px,color:#fff;
class B naios;
class C cerebras;
Conclusion
The bottleneck of inference in artificial intelligence has been overcome. Cerebras AI, with its revolutionary CS-4 and its wafer-scale hardware approach, has demonstrated that it is possible to run cutting-edge AIEdge AIRun AI directly on the device, without relying on the cloud models at speeds that mimic the fluidity of human thought.
From accelerating drug discovery to enabling real-time software creation, Cerebras is empowering developers to build what was once impossible. And by integrating this raw power with intelligent management platforms like naios.net, any company can now deploy, control, and scale next-generation AI applications with unprecedented ease, speed, and cost-effectiveness. The future of ultra-fast AI is already here, and it is time to build on it.